Table library
The numbers, ready to reuse.
Every table has a stable share URL, responsive embed, CSV export, and pixel-faithful PNG.
Table 01 · Pilot results
PoolTogether pilot metrics
| Metric | GPT-5.6 Sol | Grok 4.6 Build |
|---|---|---|
| Detection score | 100% | 0.1% |
| Recall | 100% | 50% |
| Precision | 66.7% | 25% |
| Wall time | 8m 26s | 26m 7s |
| Processed tokens | 813k | 3.95m |
| Estimated cost | $1.32 | $3.24 |
Harnesses differed. Ground truth was manually reconstructed; cost bases are not invoice-equivalent.
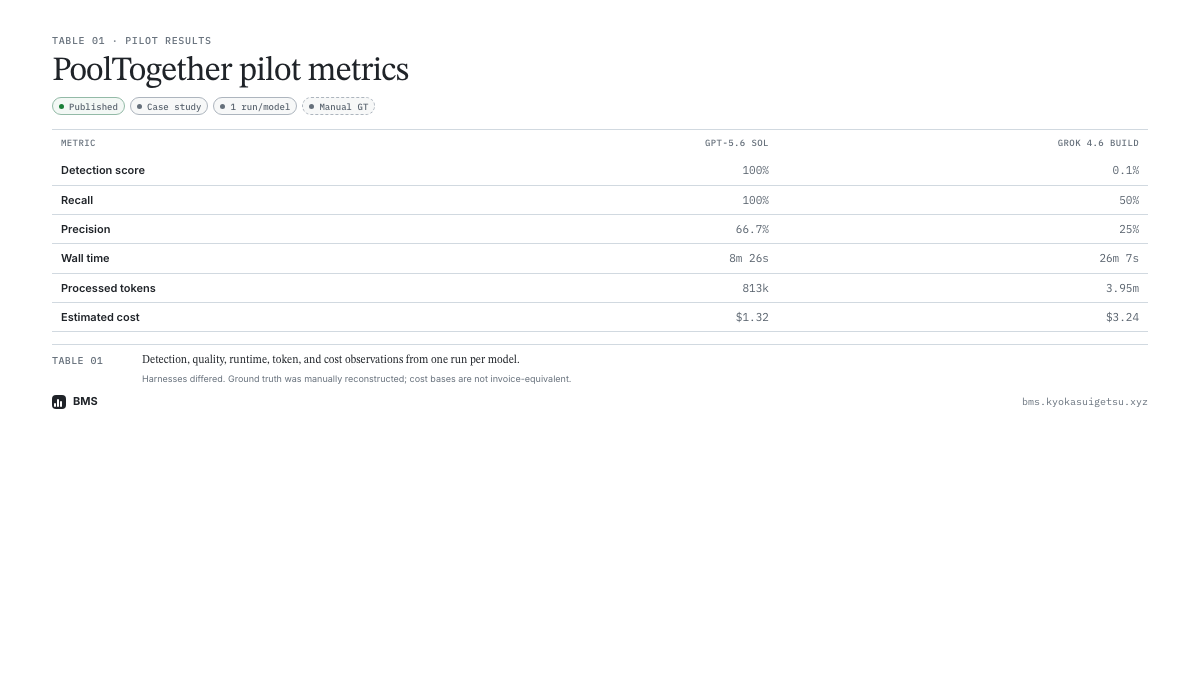
Table 02 · Reconstructed quality
Reference-based quality metrics
| Reconstructed metric | GPT-5.6 Sol · High | Grok 4.6 Build · High |
|---|---|---|
| Reference detections | 52/129 | 47/129 |
| Micro recall | 40.31% | 36.43% |
| Macro audit recall | 46.06% | 41.81% |
| Award-weighted recall | 6.81% | 4.78% |
| Closed-world precision | 50.49% | 45.63% |
| Closed-world F1 | 44.83% | 40.52% |
Codex-reconstructed manual scoring, not official API-backed EVMbench grading. Conventional accuracy is undefined.
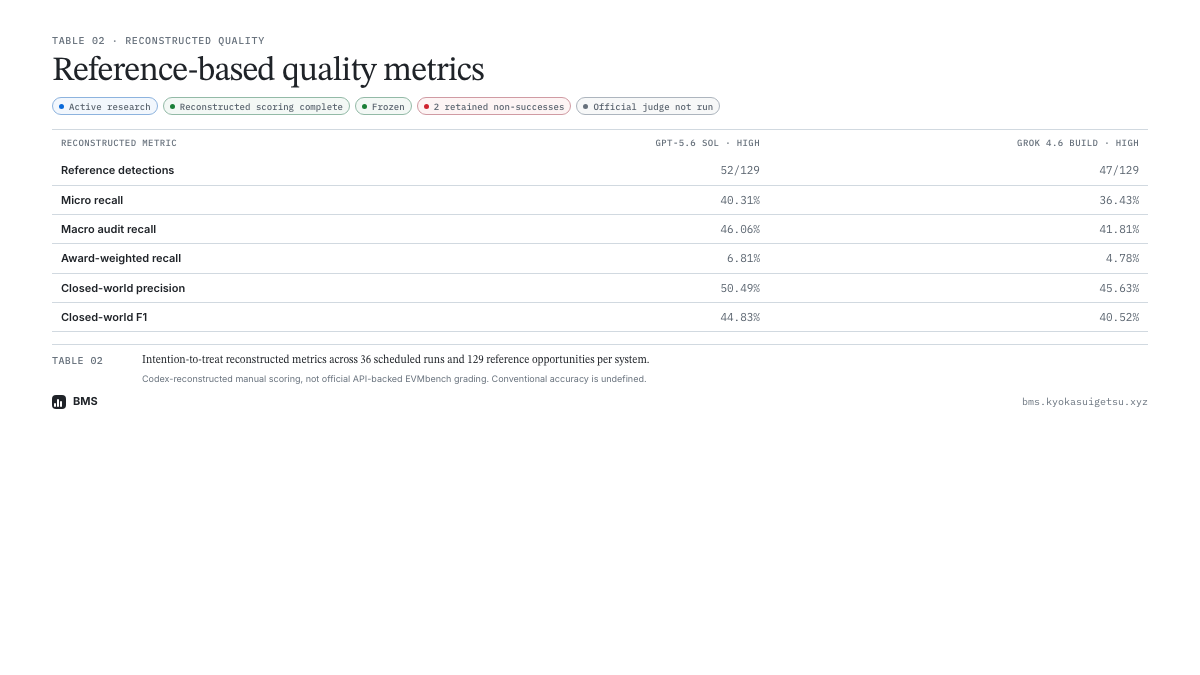
Table 03 · Finding dispositions
Reference matches and novel-valid findings
| Finding disposition | GPT-5.6 Sol · High | Grok 4.6 Build · High |
|---|---|---|
| TP / FP / FN, closed world | 52 / 51 / 77 | 47 / 56 / 82 |
| Novel-valid findings | 49 | 51 |
| Expert-validity precision | 98.06% | 96.12% |
| Conventional accuracy | N/A | N/A |
An unmatched finding is not automatically invalid. Conventional accuracy is undefined for this open-ended audit task.
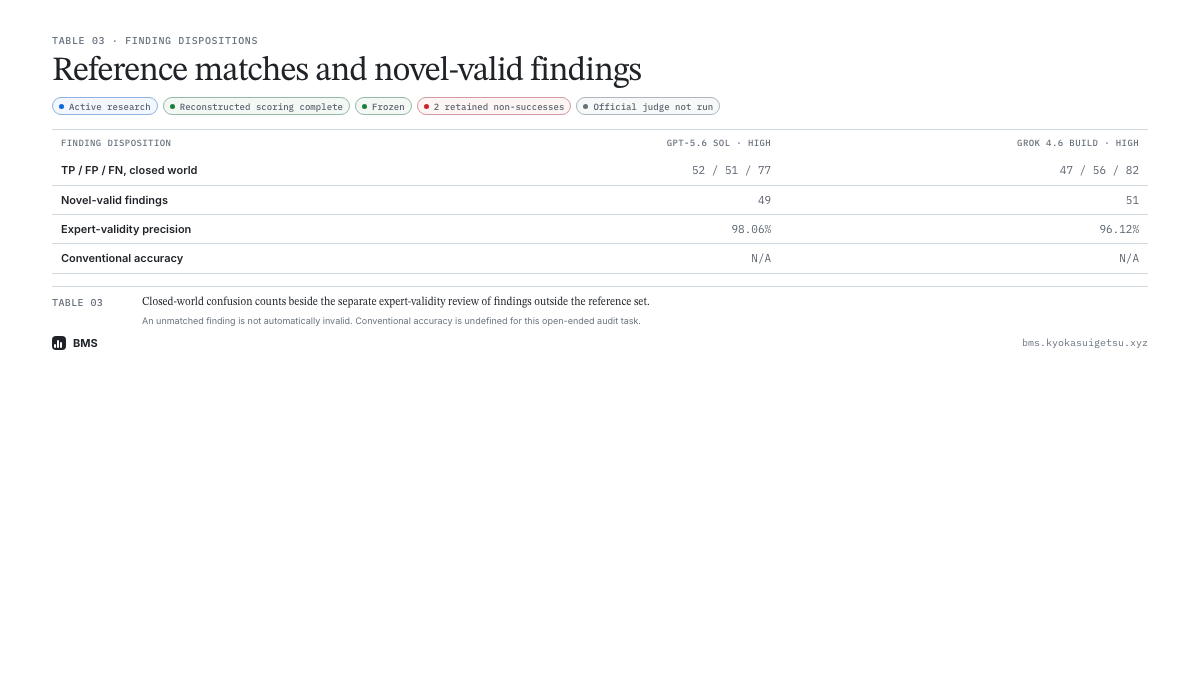
Table 04 · Paired inference
Reconstructed effects and uncertainty
| Paired reconstructed endpoint | GPT minus Grok | 95% CI | Exact p |
|---|---|---|---|
| Award-weighted recall, primary | 8.83 pp | -6.88 to 25.48 pp | 0.1484 |
| Micro reference recall | 4.26 pp | -5.32 to 14.35 pp | 0.3359 |
| Closed-world precision | 6.95 pp | -11.17 to 21.94 pp | 0.4150 |
| Closed-world F1 | 7.01 pp | -2.71 to 16.30 pp | 0.1055 |
The primary interval crosses zero. These are reconstructed manual estimates, not official EVMbench results.
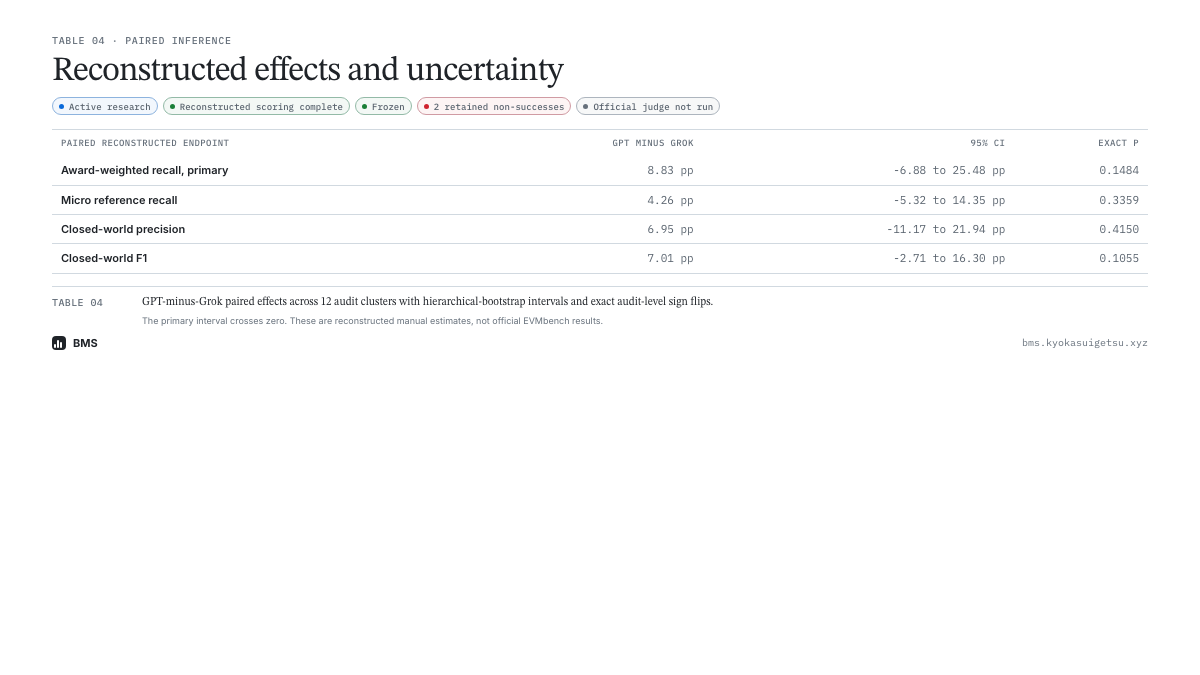
Table 05 · Frozen protocol
Controlled campaign design
| Dimension | Frozen design |
|---|---|
| Systems | GPT-5.6 Sol · High via Codex CLI; Grok 4.6 Build · High via Grok CLI |
| Sample | 12 audits × 3 replicates × 2 systems = 72 assignments |
| User input | Byte-identical prompt and deterministic source bundle within each paired block |
| Access | No task tools, shell, web, browser, plugins, skills, memory, workflows, or subagents |
| Runtime | Fresh workspace and session; sequential runs on the same Apple Silicon host |
| Timeout | 1,800 seconds from launch to final response |
| Output | One final Markdown audit report captured by the harness |
Provider system prompts, tokenizers, CLIs, compaction, safety routing, and cloud backends remain system-level differences.
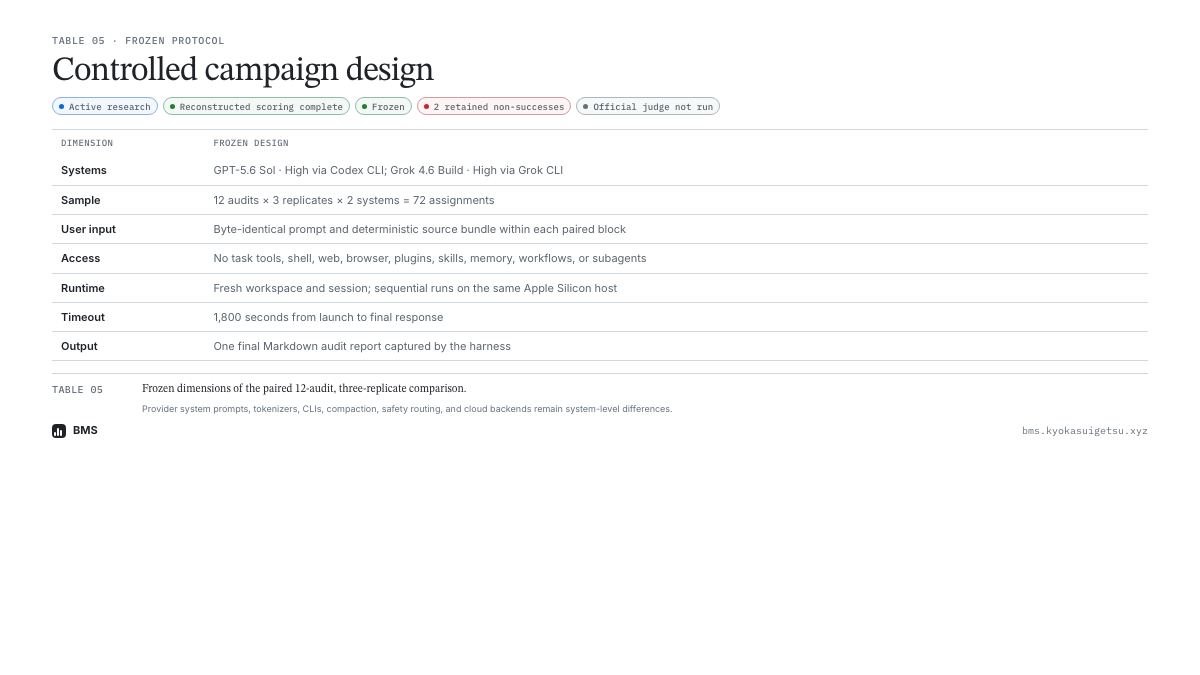
Table 06 · Operational summary
Runtime, tokens, and recorded cost
| System | Median wall | Mean tokens | Total tokens | Mean cost | Total cost |
|---|---|---|---|---|---|
| GPT-5.6 Sol · High | 4m 24s | 99.87k | 3.5m | $0.75 (API-equivalent) | $26.08 |
| Grok 4.6 Build · High | 10m 25s | 124.16k | 4.35m | $0.41 (provider-reported) | $14.31 |
Grok cost is provider-reported; GPT-5.6 Sol cost is API-equivalent. The two price bases are not invoice-equivalent.
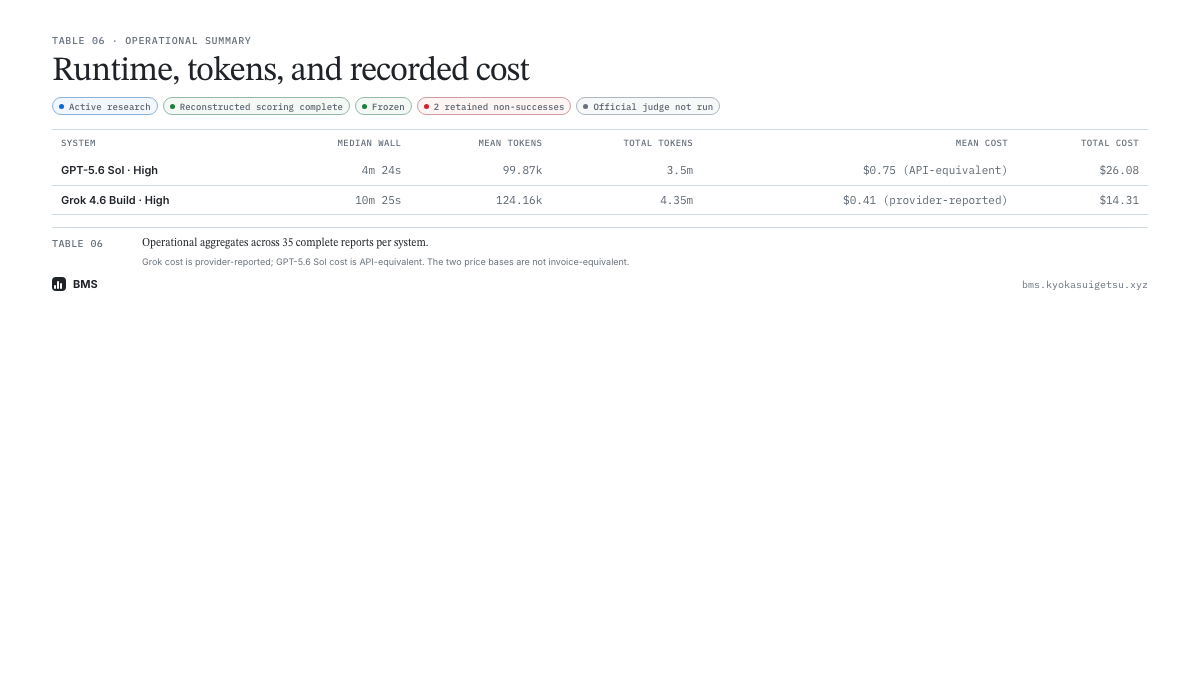
Table 07 · Frozen integrity
Collection and pairing checks
| Integrity check | State |
|---|---|
| Terminal assignments | 72 of 72 |
| Frozen reports | 70 complete reports plus 2 retained non-success outcomes |
| Paired blocks | 36 complete; 0 unpaired |
| Ground truth opened during collection | No |
| PoolTogether pilot included | No |
Both non-successes remain in the frozen ledger and intention-to-treat denominators.
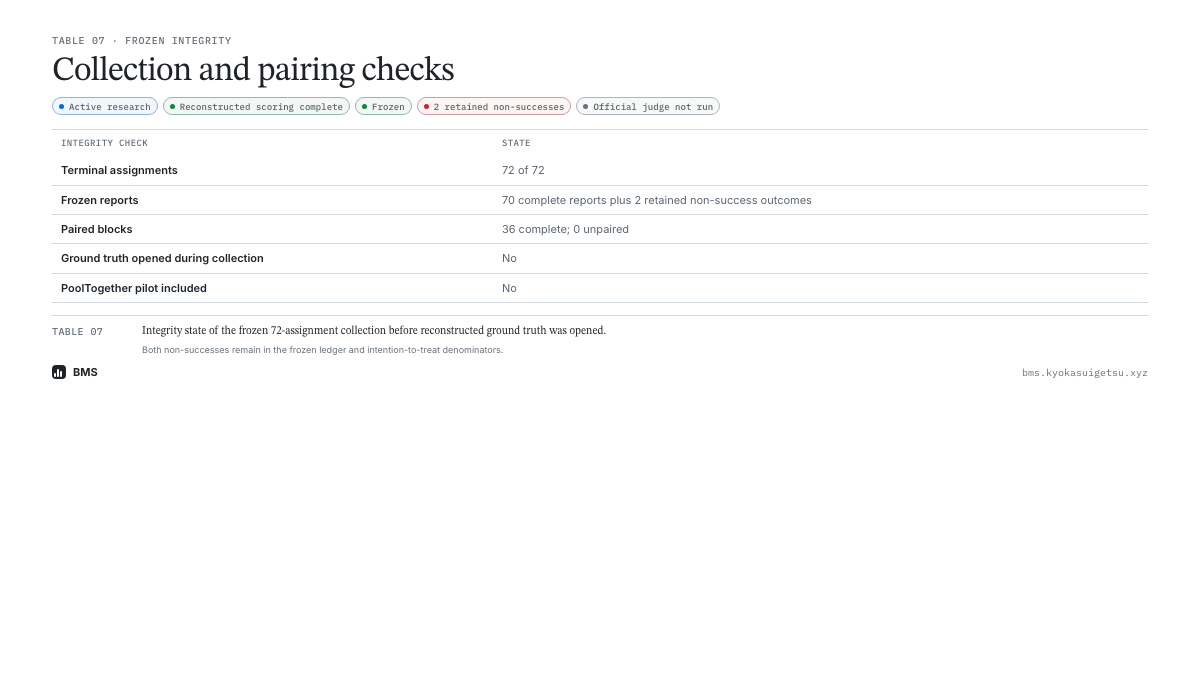
Table 09 · Verified-proof outcomes
Verified proofs per task and condition
| Task (family) | Tool-assisted | Static (no tools) | Budgeted triage |
|---|---|---|---|
| share-inflation (asset/share rounding) | pending | pending | pending |
| reentrancy-withdraw (external-call ordering) | pending | pending | pending |
| uninitialized-treasury (initialization authorization) | pending | pending | pending |
Local feasibility study, 6 replicates per cell; not an official EVMbench score. Cells with no terminal run read "pending", never zero.
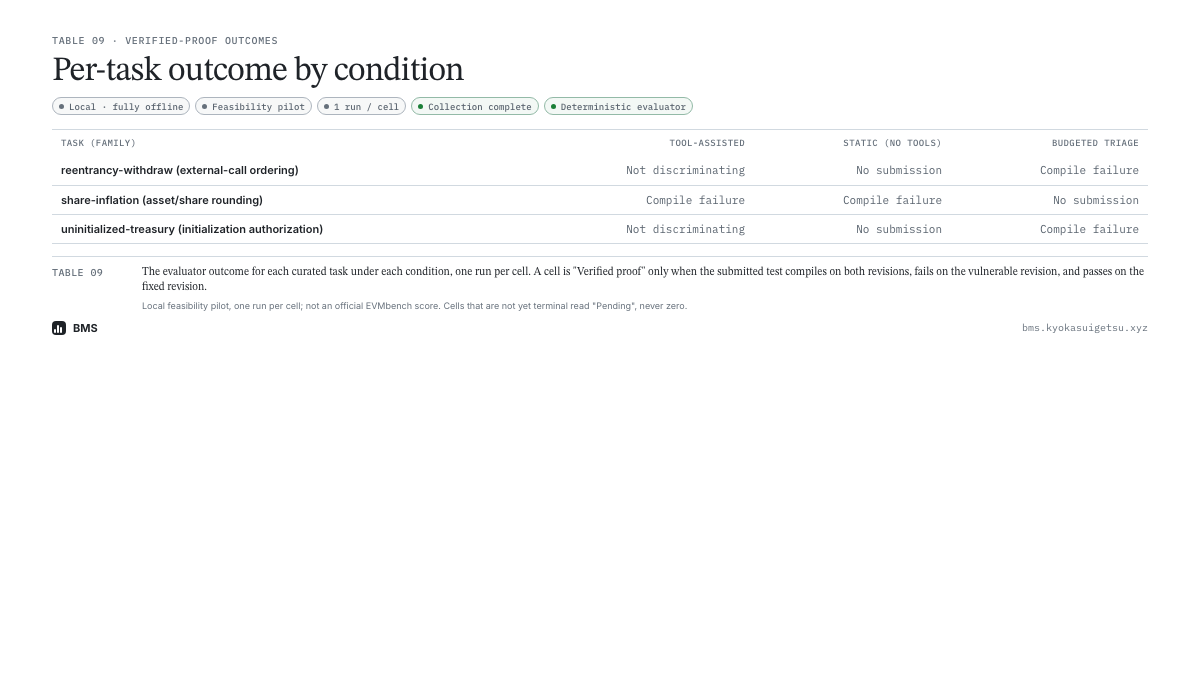
Table 10 · Verified-proof rate
Verified-proof rate by condition
| Condition | Agent access | Terminal | Verified | Rate | 95% CI |
|---|---|---|---|---|---|
| Tool-assisted | Bounded search/read + forge build/test feedback, then one submitted proof | 0 | pending | pending | pending |
| Static (no tools) | Full source context (target + provided test harness); no tool feedback | 0 | pending | pending | pending |
| Budgeted triage | A strict budget of four inspect operations, then one submission | 0 | pending | pending | pending |
The CI clusters on three tasks, so intervals are wide by construction. Quality is pending until a condition is fully terminal; pending is never shown as zero. This is an agent-system study, not a model leaderboard.
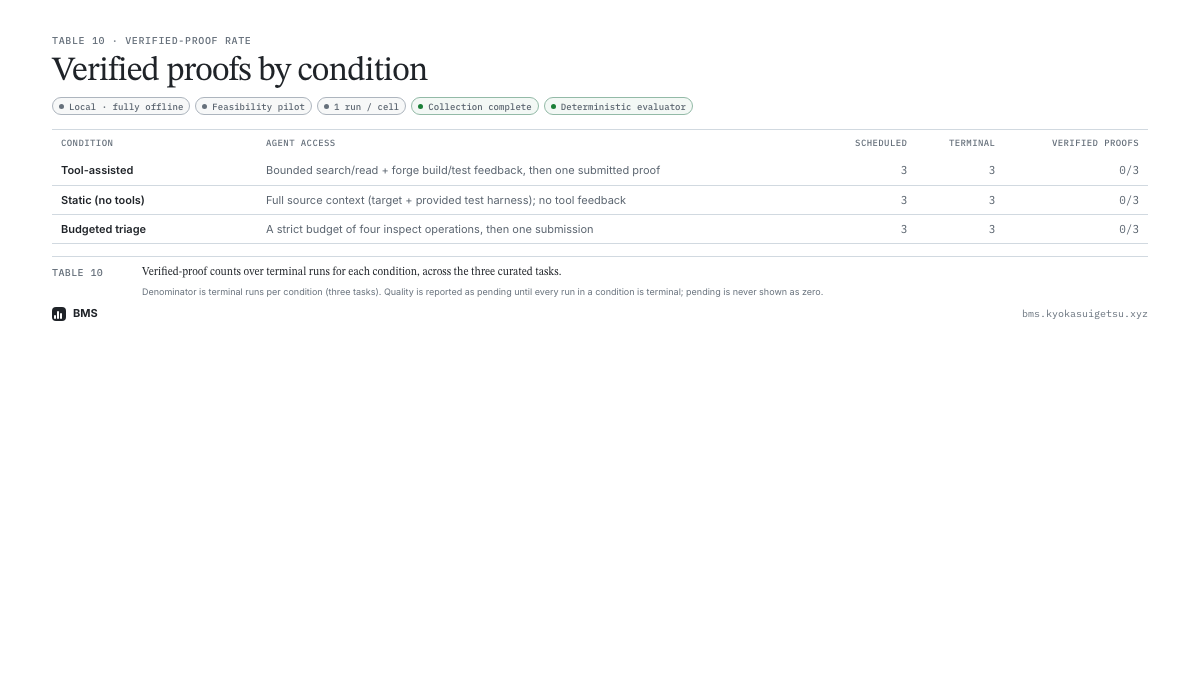
Table 11 · Frozen protocol
Conditions and budgets
| Condition | Agent access | Turn / tool budget | Wall cap |
|---|---|---|---|
| Tool-assisted | Bounded search/read + forge build/test feedback, then one submitted proof | 12 turns / 10 tools | 1200 s |
| Static (no tools) | Full source context (target + provided test harness); no tool feedback | 3 turns / 0 tools | 900 s |
| Budgeted triage | A strict budget of four inspect operations, then one submission | 6 turns / 4 tools | 900 s |
The agent receives only the vulnerable workspace; the fixed revision is never mounted. Foundry ffi and filesystem permissions are disabled in every task.
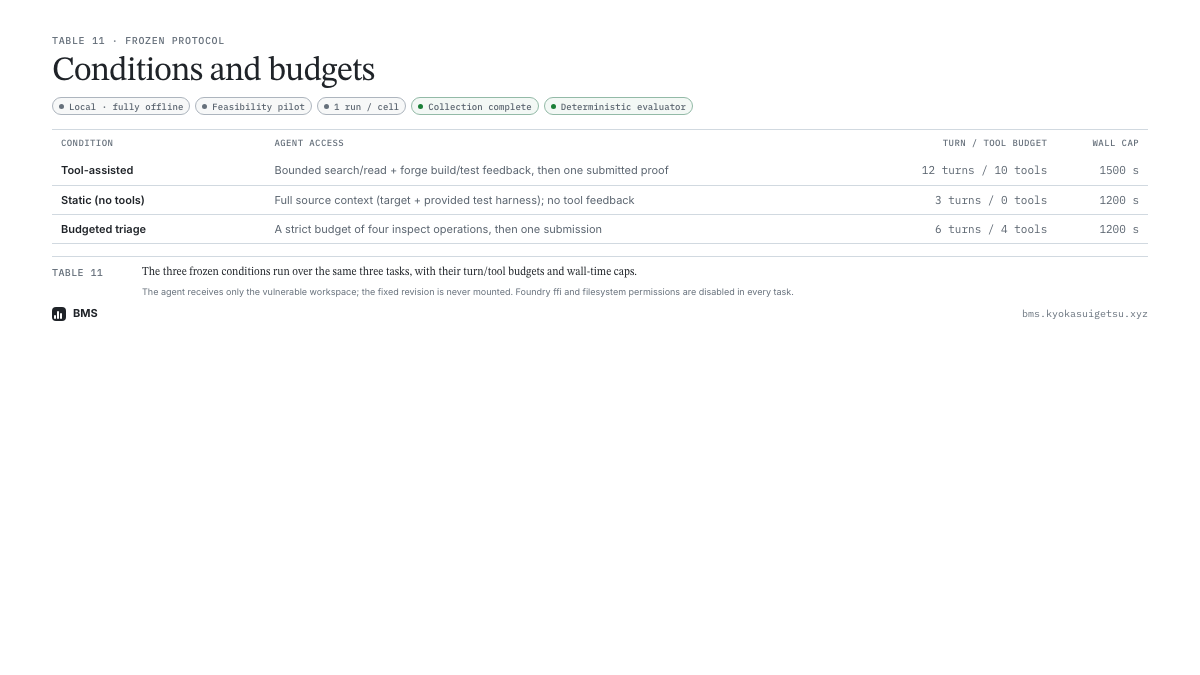
Table 12 · Model & runtime lock
Frozen local model and runtime
| Field | Value |
|---|---|
| Requested spec | Qwen/Qwen3.8-27B-FP8 |
| Served locally | qwen3.8:27b → alias qwen3.8-27b-local |
| Quantization | Q4_K_M (requested FP8) |
| Architecture | qwen35 · 27.32B params |
| Context length | 262144 native · served at 8192 |
| Runtime engine | Ollama 0.32.14, loopback 127.0.0.1:11435, cloud disabled |
| Host | Apple M4 Pro · 24 GB unified memory · arm64 |
| Sampling | think=false, temperature=1, top_p=0.95, num_predict=4096 |
| Replicates | 6 per cell · seed = 1000 + replicate |
| Harness version | v2 (forge-std-subset test base) |
| Manifest SHA-256 | ec9bb426e93b2300 |
The requested FP8 spec and native 262144-token context do not fit 24 GB; the same model is served at Q4_K_M with an 8192-token context. This is a documented adaptation, not a different model and not a cloud fallback. No native long-context performance is claimed.
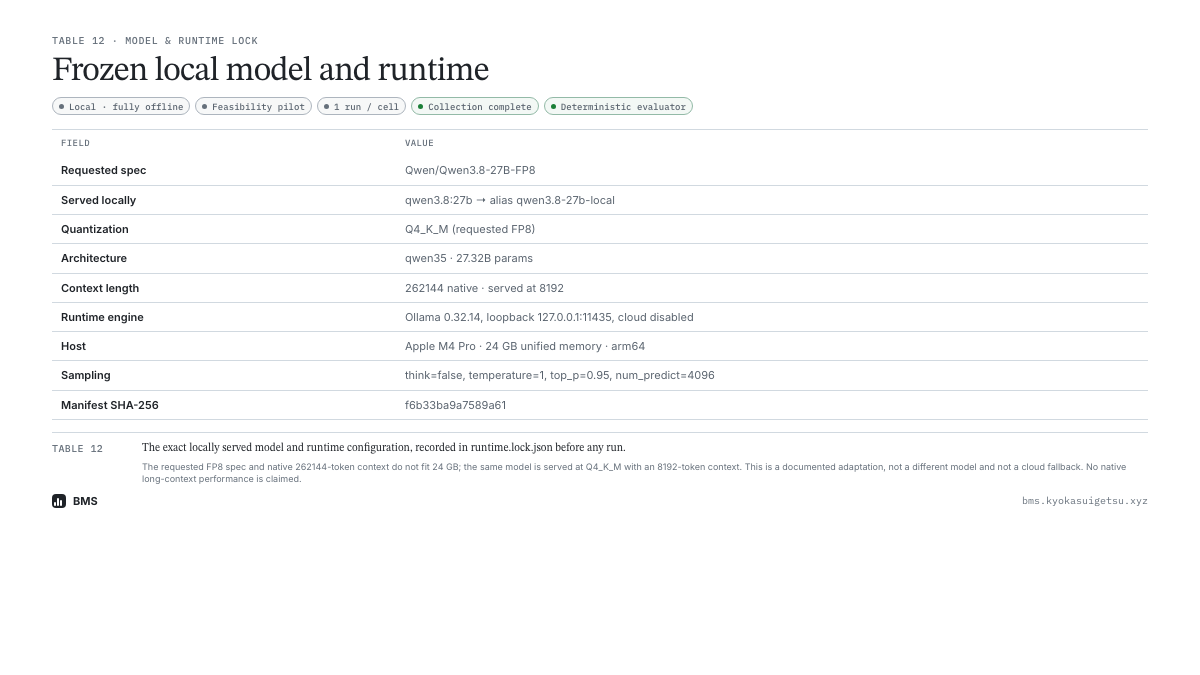
Table 13 · Operational telemetry
Wall time, generated tokens, and localisation
| Metric | Value |
|---|---|
| Median wall time / run | pending |
| Total collection wall time | pending |
| Generated tokens (total) | pending |
| Generated tokens (median / run) | pending |
| Tool calls (total) | pending |
| Source localised (tool-enabled runs) | pending |
Operational telemetry is kept separate from the verified-proof endpoint. Wall time and generated tokens do not prove correctness. Pending cells are never shown as zero.
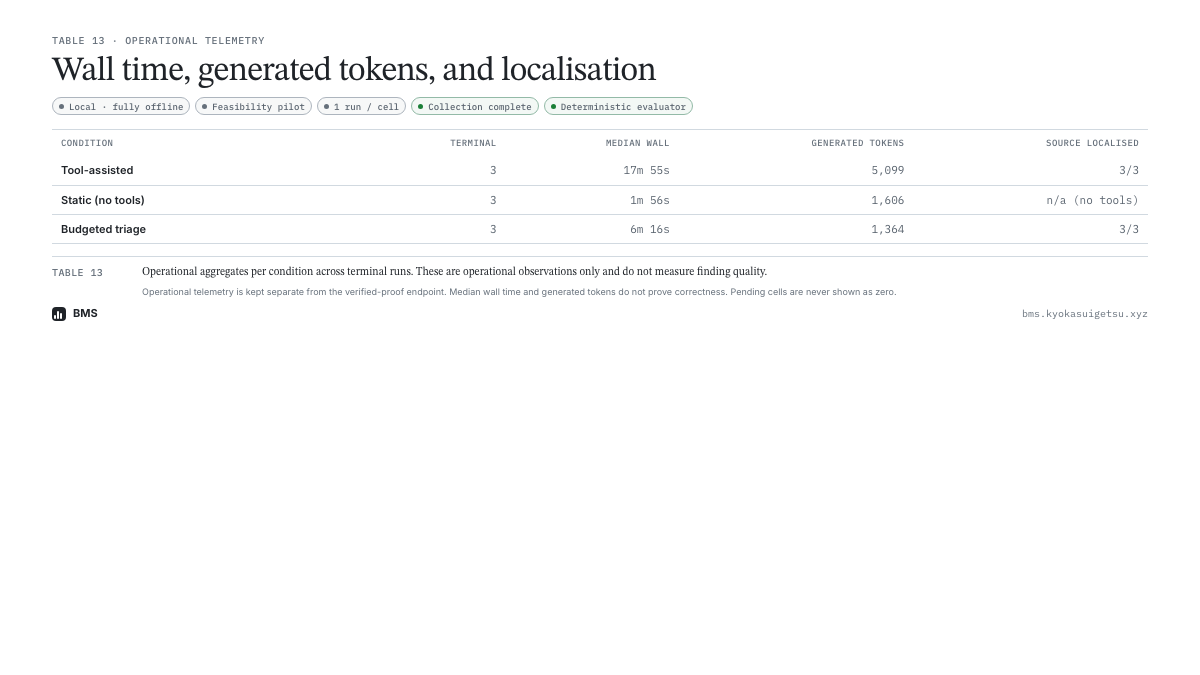
Table 14 · GLM-5.3 verified proofs
GLM-5.3 (ZCode) verified proofs per task and condition
| Task (family) | Tool-assisted | Static (no tools) | Budgeted triage |
|---|---|---|---|
| share-inflation (asset/share rounding) | 1/1 | 1/1 | 1/1 |
| reentrancy-withdraw (external-call ordering) | 1/1 | 1/1 | 1/1 |
| uninitialized-treasury (initialization authorization) | 1/1 | 1/1 | 1/1 |
Agent-system arm (GLM-5.3 + ZCode harness), n = 1 run per cell, same fixtures and frozen evaluator as the local pilot; operator-role contamination is disclosed in the report. Cells with no terminal run read "pending", never zero. Not an official EVMbench score.
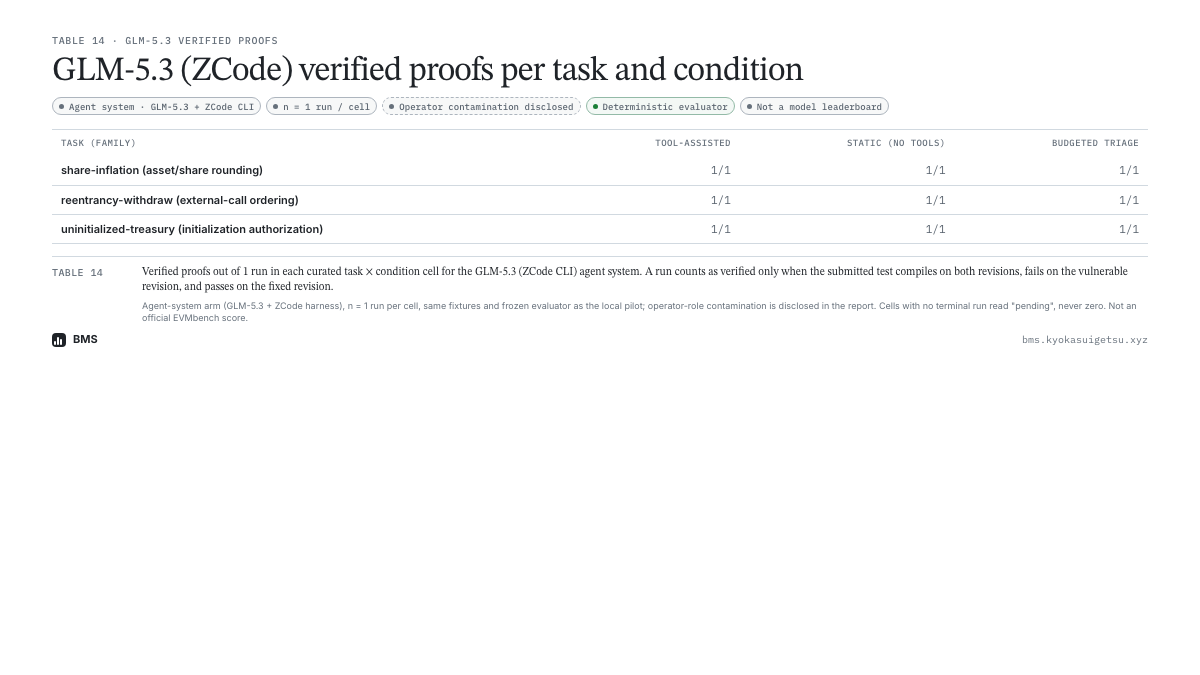
Table 15 · GLM-5.3 verified-proof rate
GLM-5.3 (ZCode) verified-proof rate by condition
| Condition | Agent access | Terminal | Verified | Rate | 95% CI |
|---|---|---|---|---|---|
| Tool-assisted | Bounded search/read + forge build/test feedback, then one submitted proof | 3 | 3/3 | 100% | 100–100% |
| Static (no tools) | Full source context (target + provided test harness); no tool feedback | 3 | 3/3 | 100% | 100–100% |
| Budgeted triage | A strict budget of four inspect operations, then one submission | 3 | 3/3 | 100% | 100–100% |
The interval is degenerate at 9/9 and n is 1 per cell: this is a descriptive result only, with no inferential claim. Condition-level contrasts are confounded by within-session carryover (tools ran before static and triage).
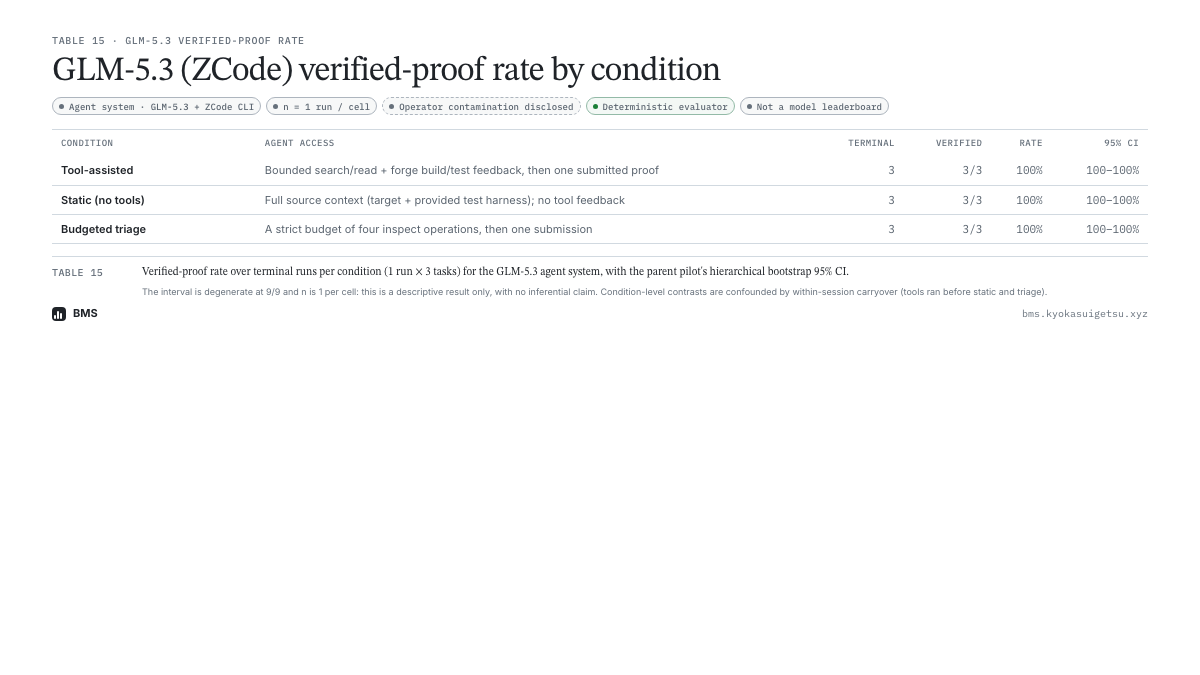
Table 16 · Frozen arm protocol
GLM-5.3 arm conditions and budgets
| Condition | Agent access | Turn / tool budget | Wall cap |
|---|---|---|---|
| Tool-assisted | Bounded search/read + forge build/test feedback, then one submitted proof | 12 turns / 10 tools | 1500 s |
| Static (no tools) | Full source context (target + provided test harness); no tool feedback | 3 turns / 0 tools | 1200 s |
| Budgeted triage | A strict budget of four inspect operations, then one submission | 6 turns / 4 tools | 1200 s |
Wall time runs begin→final and includes GLM-5.3 + ZCode inference between turns. The agent interacts with the task workspace only through the driver, which enforces the parent action policy; the fixed revision is never mounted.
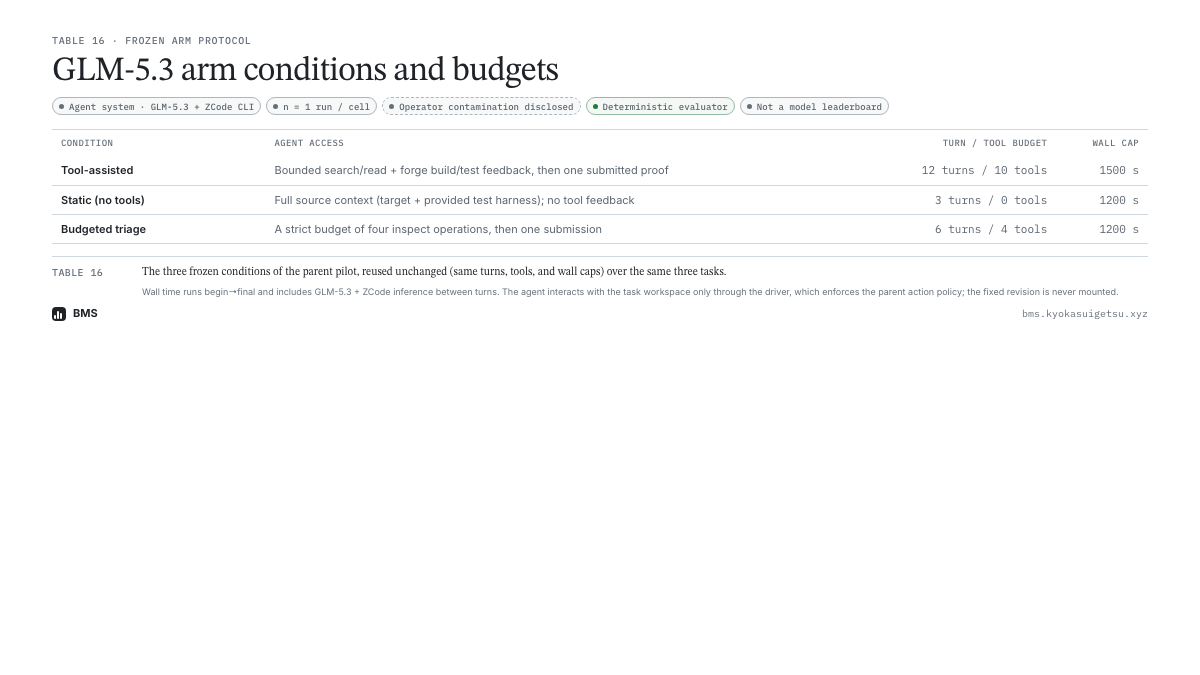
Table 17 · Agent-system lock
Frozen GLM-5.3 + ZCode agent-system lock
| Field | Value |
|---|---|
| Model identifier | builtin:zai-start-plan/GLM-5.3 |
| Runtime engine | ZCode CLI/desktop harness (one stateful session) |
| ZCode app | 3.8.1 · CLI bundle sha256 9318f60fb8c2c3bc… |
| Provider | zai (OAuth), Anthropic-compatible endpoint |
| Reported limits | context 1,000,000 · output 128,000 |
| Inference control | none (no seed, no sampler control) |
| Token metering | not available — recorded n/a, never zero |
| Sandbox | Docker --network none · cap-drop ALL · no-new-privileges · solc 0.8.35 |
| Host | Apple M4 Pro · 24 GB · arm64 · macOS 27.0 |
| Lock frozen | before first run · 2026-08-21T19:59:41Z |
| Replicates | 1 per cell (deviation from parent 6/cell justified pre-run) |
Inference is cloud-served through the ZCode runtime: sampler settings are not operator-controlled and token telemetry does not exist (recorded n/a, never imputed). The arm deviates from the parent 6-replicate plan: 1 run per cell, justified before collection because a single stateful session cannot produce independent replicates.
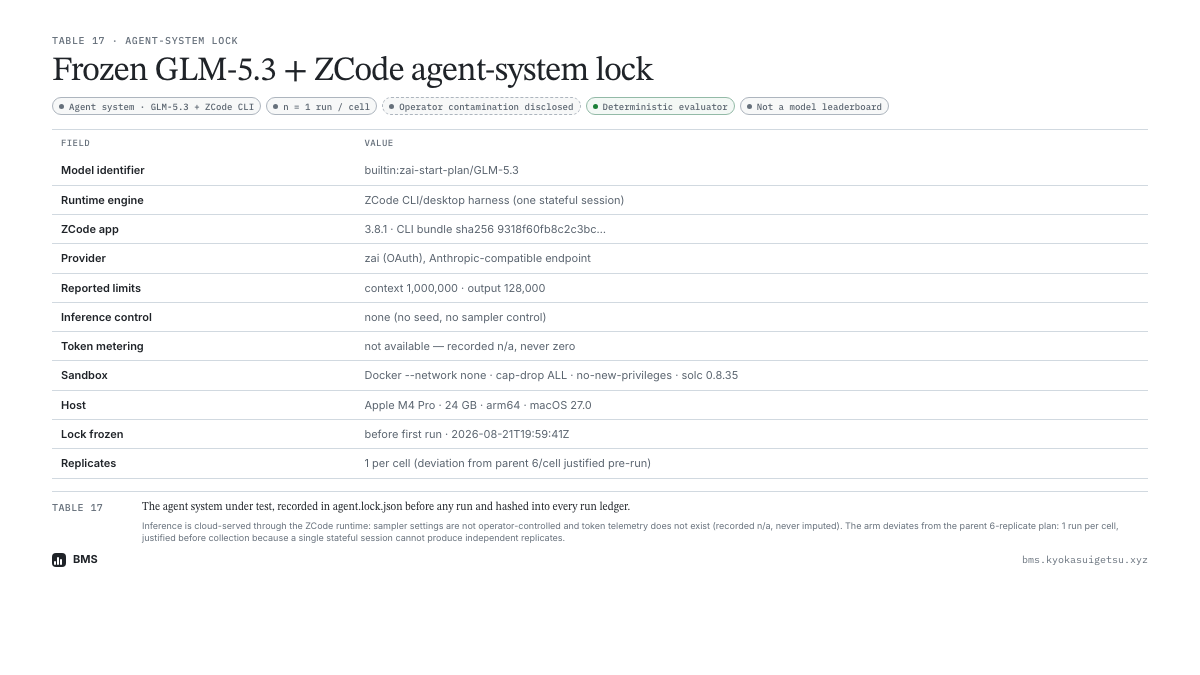
Table 18 · Operational telemetry
GLM-5.3 arm wall time, tools, and localisation
| Metric | Value |
|---|---|
| Median wall time / run | 0m 09s |
| Total collection wall time | 5m 11s |
| Generated tokens (total) | n/a (no token metering) |
| Tool calls (total) | 15 |
| Source localised (tool-enabled runs) | 6/6 |
Wall time includes GLM-5.3 + ZCode inference between turns and is not comparable to the parent pilot's automated local loop. Token telemetry does not exist for this runtime and is shown as n/a, never zero.
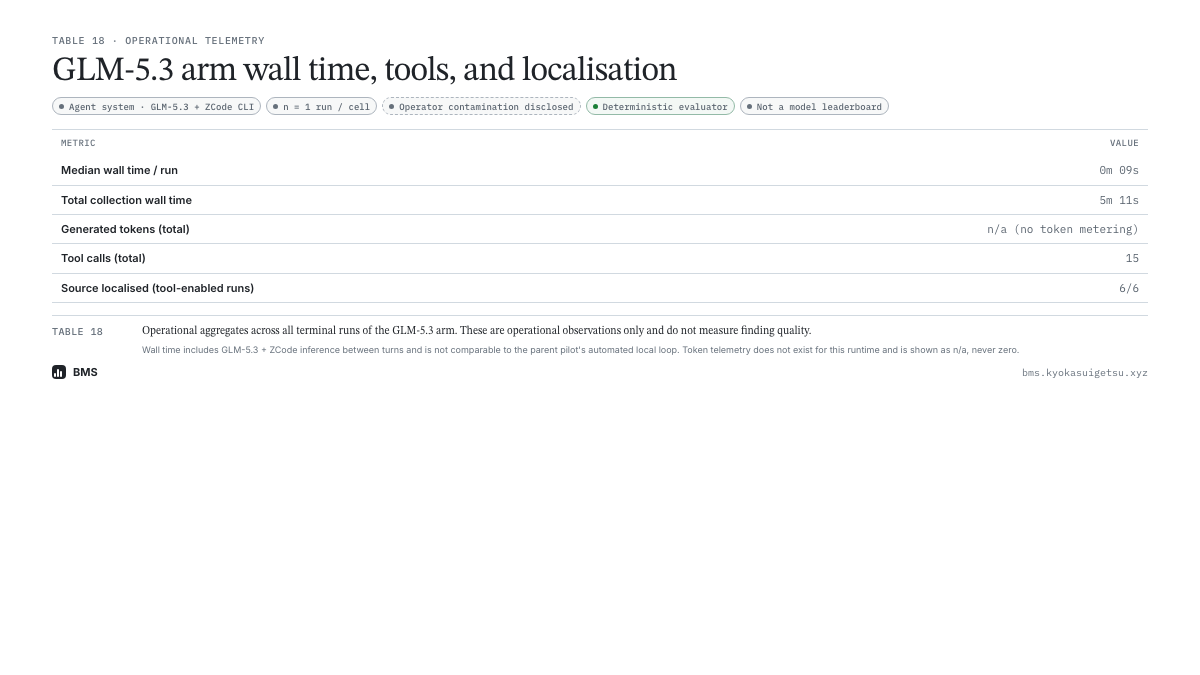
Table 19 · Adjacent arms
Local verify arms side by side (never pooled)
| Arm (agent system) | Harness | Runs | Verified | Median wall | Primary caveat |
|---|---|---|---|---|---|
| GLM-5.3 (ZCode CLI) | v2 fairer harness | 9 | 9/9 | 0m 09s | Operator-role contamination disclosed; n = 1/cell; no token metering |
| Qwen3.8-27B · Q4_K_M (local Ollama) | v1 strict harness | 9 | 0/9 | 6m 48s | 8K-context Q4_K_M local serving, thinking disabled; strict v1 prompt |
| Qwen3.8-27B · Q4_K_M (local Ollama) (v2) | v2 fairer harness | 1 of 54 scheduled | pending | pending | Collection incomplete (2 partial run dirs); quality withheld, never zero |
These are not comparable measurements and must not be read as a leaderboard. The Qwen v2 arm (same harness generation as the GLM arm) is still collecting: its quality cells read "pending" and are never shown as zero. The controlled Grok/GPT campaign measures a different endpoint (reported findings on audits) and is excluded from this table by design.
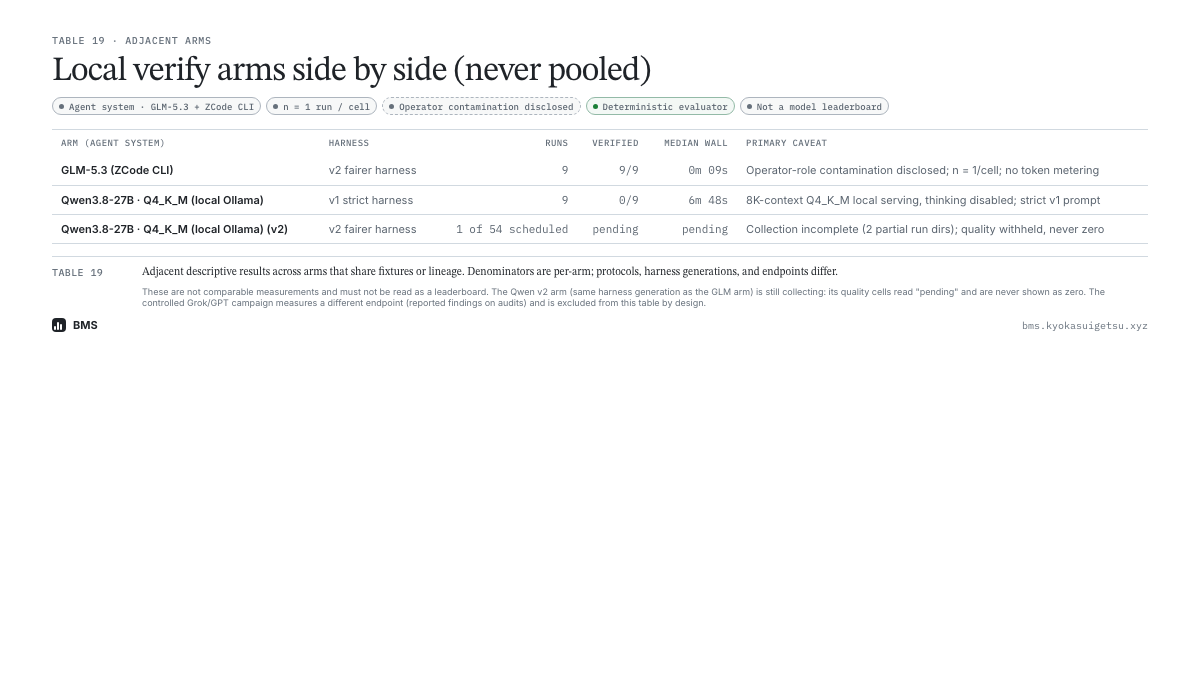
Table 20 · Adjacent cross-system
EVMBench Detect recall by agent system (never pooled)
| Agent system | Runs | Refs detected | Micro recall | Macro recall | Award-weighted | Precision (closed) | F1 (closed) | Median wall |
|---|---|---|---|---|---|---|---|---|
| GLM-5.3 · ZCode CLI 3.8.1 (self-scored) | 12 | 5/43 | 11.6% | 12.1% | 1.91% | 29.4% | 16.7% | 1m 09s |
| GPT-5.6 Sol · High (Codex CLI) | 36 | 52/129 | 40.3% | 46.1% | 6.81% | 50.5% | 44.8% | 4m 24s |
| Grok 4.6 Build · High (Grok CLI) | 36 | 47/129 | 36.4% | 41.8% | 4.78% | 45.6% | 40.5% | 10m 25s |
Adjacent descriptive results under different protocols: replicate counts (1 vs 3), scorer independence, harness CLI, and session structure all differ. The GLM column is a single-reviewer self-scored reconstruction and is not official EVMbench grading. Never pooled into one leaderboard.
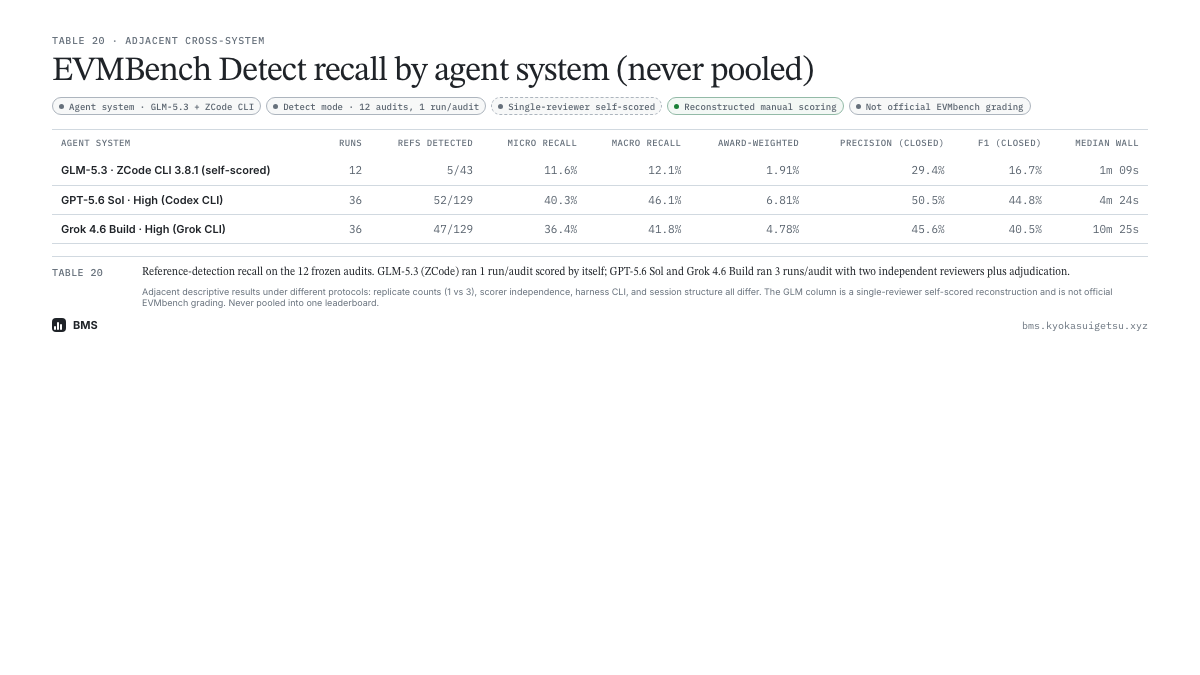
Table 21 · GLM arm outcomes
GLM-5.3 (ZCode) references detected per audit
| Audit | Refs detected | Findings reported | TP | FP (closed) | FN | Wall |
|---|---|---|---|---|---|---|
| NextGen (NFT minter) | 0/2 | 4 | 0 | 4 | 2 | 3m 04s |
| Ethereum Credit Guild (lending) | 1/2 | 2 | 1 | 1 | 1 | 3m 13s |
| Curves (social tokens) | 3/4 | 2 | 3 | 0 | 1 | 1m 01s |
| reNFT (rental escrow) | 0/6 | 2 | 0 | 2 | 6 | 2m 06s |
| Taiko (rollup) | 1/5 | 2 | 1 | 1 | 4 | 2m 29s |
| Size (credit market) | 0/4 | 1 | 0 | 1 | 4 | 1m 09s |
| Basin (AMM) | 0/2 | 0 | 0 | 0 | 2 | 1m 01s |
| Phi (creator creds) | 0/6 | 1 | 0 | 1 | 6 | 0m 53s |
| Wildcat (credit vault) | 0/1 | 0 | 0 | 0 | 1 | 0m 33s |
| Forte (float math) | 0/5 | 0 | 0 | 0 | 5 | 0m 39s |
| Virtuals (agent protocol) | 0/4 | 1 | 0 | 1 | 4 | 1m 45s |
| Panoptic (options vault) | 0/2 | 1 | 0 | 1 | 2 | 0m 40s |
Single-reviewer self-scored reconstruction; not official EVMbench grading. Reported findings that matched no reference are closed-world false positives; their expert validity was not adjudicated.
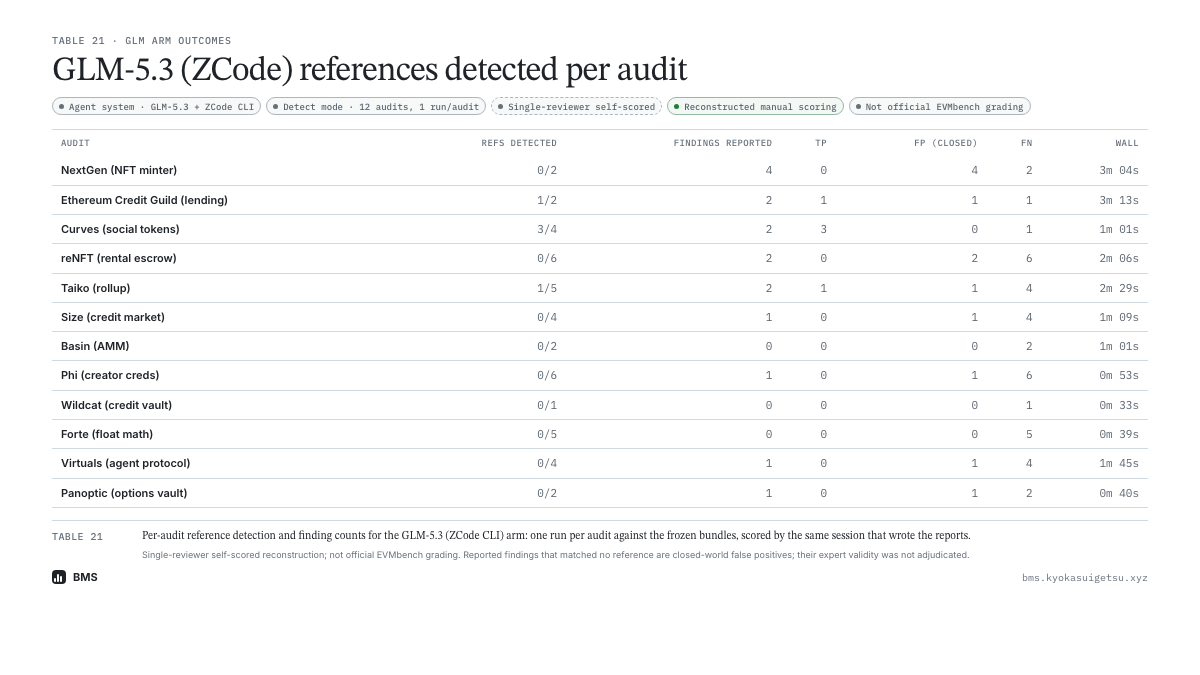
Table 22 · Adjacent cross-system
EVMBench Detect recall by agent system, four arms (never pooled)
| Agent system | Runs | Refs detected | Micro recall | Macro recall | Award-weighted | Precision (closed) | F1 (closed) | Median wall |
|---|---|---|---|---|---|---|---|---|
| Ox Alpha · OpenCode 1.18.20 (self-scored) | 12 | 4/43 | 9.3% | 7.6% | 1.03% | 25.0% | 13.6% | 2m 50s |
| GPT-5.6 Sol · High (Codex CLI) | 36 | 52/129 | 40.3% | 46.1% | 6.81% | 50.5% | 44.8% | 4m 24s |
| Grok 4.6 Build · High (Grok CLI) | 36 | 47/129 | 36.4% | 41.8% | 4.78% | 45.6% | 40.5% | 10m 25s |
| GLM-5.3 · ZCode CLI 3.8.1 (self-scored) | 12 | 5/43 | 11.6% | 12.1% | 1.91% | 29.4% | 16.7% | 1m 09s |
Adjacent descriptive results under different protocols: replicate counts (1 vs 3), scorer independence, harness CLI, and session structure all differ. Ox and GLM columns are single-reviewer self-scored reconstructions, not official EVMbench grading. The Ox figure is the clean-room v3 run (pre-freeze blindness held); two earlier answer-key-contaminated attempts were discarded and archived. Never pooled into one leaderboard.
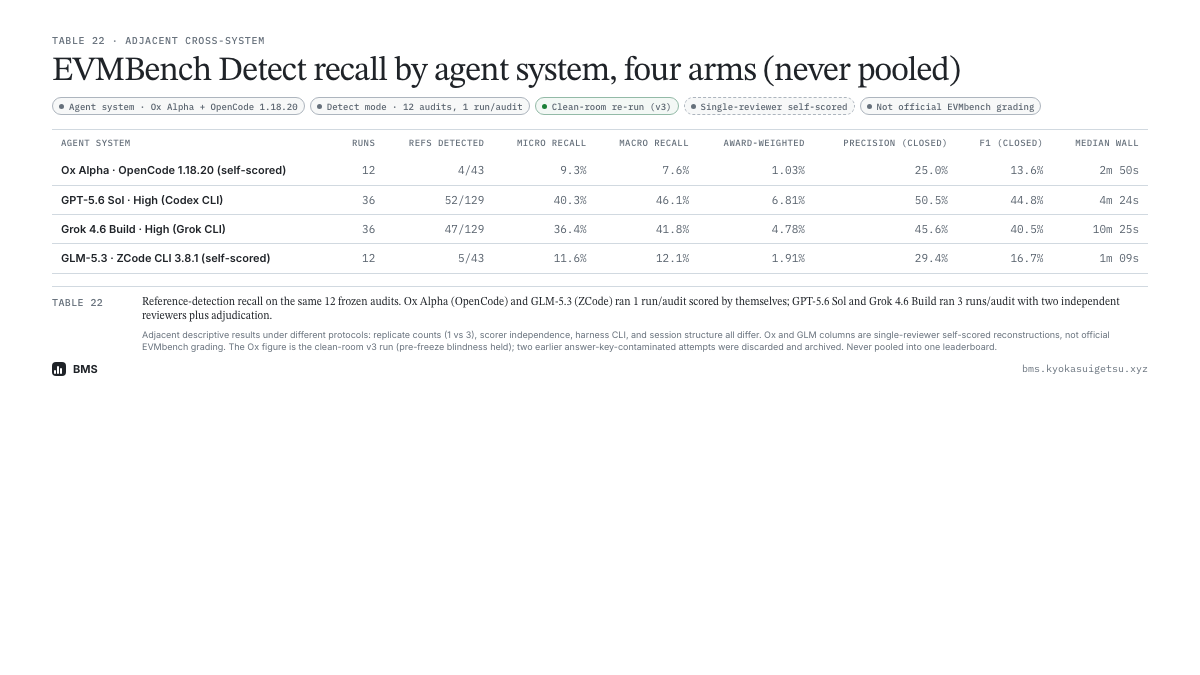
Table 23 · Ox Alpha arm outcomes
Ox Alpha (OpenCode) references detected per audit
| Audit | Refs detected | Findings reported | TP | FP (closed) | FN | Wall |
|---|---|---|---|---|---|---|
| NextGen (NFT minter) | 0/2 | 7 | 0 | 7 | 2 | 4m 23s |
| Ethereum Credit Guild (lending) | 0/2 | 2 | 0 | 2 | 2 | 10m 41s |
| Curves (social tokens) | 3/4 | 3 | 3 | 1 | 1 | 2m 50s |
| reNFT (rental escrow) | 0/6 | 0 | 0 | 0 | 6 | 5m 40s |
| Taiko (rollup) | 0/5 | 0 | 0 | 0 | 5 | 18m 10s |
| Size (credit market) | 0/4 | 0 | 0 | 0 | 4 | 1m 34s |
| Basin (AMM) | 0/2 | 0 | 0 | 0 | 2 | 1m 13s |
| Phi (creator creds) | 1/6 | 1 | 1 | 0 | 5 | 1m 22s |
| Wildcat (credit vault) | 0/1 | 0 | 0 | 0 | 1 | 0m 58s |
| Forte (float math) | 0/5 | 0 | 0 | 0 | 5 | 0m 49s |
| Virtuals (agent protocol) | 0/4 | 2 | 0 | 2 | 4 | 5m 59s |
| Panoptic (options vault) | 0/2 | 0 | 0 | 0 | 2 | 1m 39s |
Single-reviewer self-scored reconstruction from the clean-room v3 run (pre-freeze blindness held); not official EVMbench grading. Reported findings that matched no reference are closed-world false positives; their expert validity was not adjudicated.
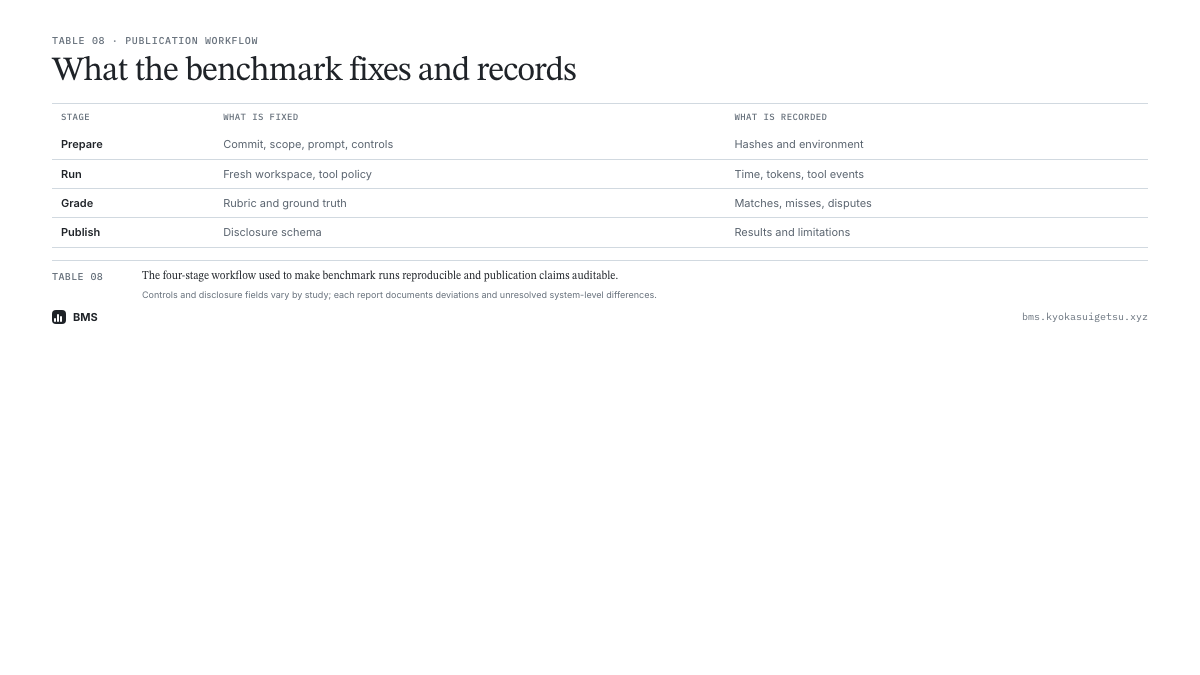
Table 08 · Publication workflow
What the benchmark fixes and records
| Stage | What is fixed | What is recorded |
|---|---|---|
| Prepare | Commit, scope, prompt, controls | Hashes and environment |
| Run | Fresh workspace, tool policy | Time, tokens, tool events |
| Grade | Rubric and ground truth | Matches, misses, disputes |
| Publish | Disclosure schema | Results and limitations |
Controls and disclosure fields vary by study; each report documents deviations and unresolved system-level differences.