Shareable benchmark table
Frozen local model and runtime
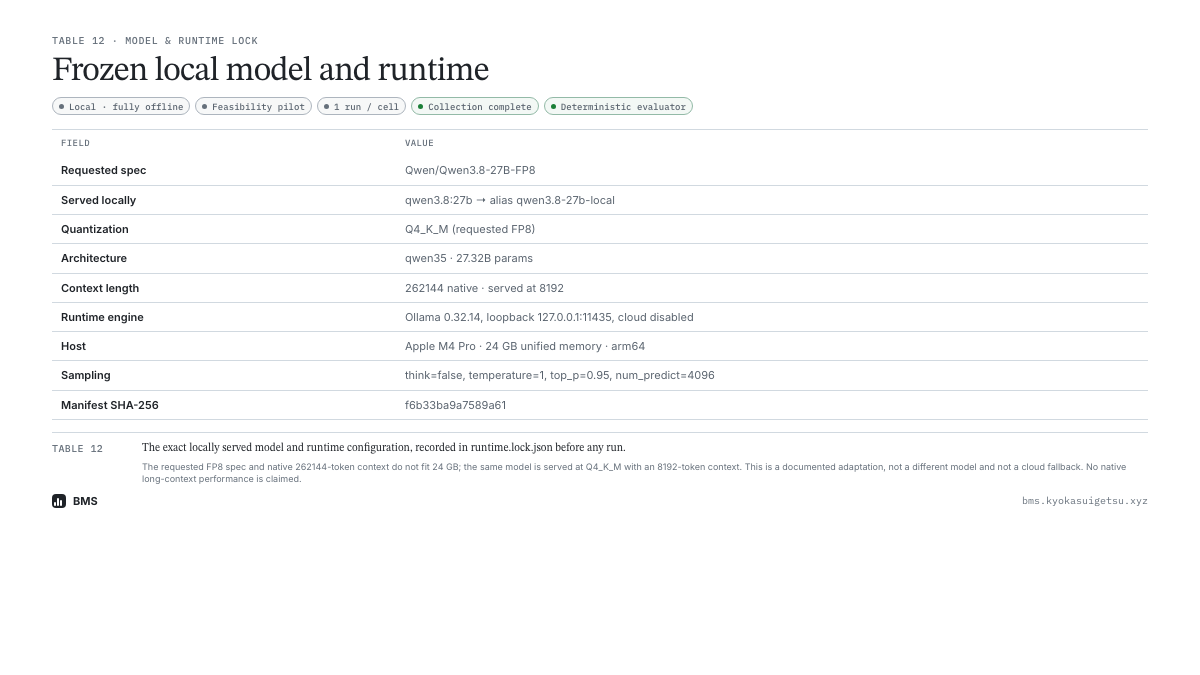
The exact locally served model and runtime configuration, recorded in runtime.lock.json before any run.
Table 12 · Model & runtime lock
Frozen local model and runtime
| Field | Value |
|---|---|
| Requested spec | Qwen/Qwen3.8-27B-FP8 |
| Served locally | qwen3.8:27b → alias qwen3.8-27b-local |
| Quantization | Q4_K_M (requested FP8) |
| Architecture | qwen35 · 27.32B params |
| Context length | 262144 native · served at 8192 |
| Runtime engine | Ollama 0.32.14, loopback 127.0.0.1:11435, cloud disabled |
| Host | Apple M4 Pro · 24 GB unified memory · arm64 |
| Sampling | think=false, temperature=1, top_p=0.95, num_predict=4096 |
| Replicates | 6 per cell · seed = 1000 + replicate |
| Harness version | v2 (forge-std-subset test base) |
| Manifest SHA-256 | ec9bb426e93b2300 |
The requested FP8 spec and native 262144-token context do not fit 24 GB; the same model is served at Q4_K_M with an 8192-token context. This is a documented adaptation, not a different model and not a cloud fallback. No native long-context performance is claimed.