Shareable benchmark table
EVMBench Detect recall by agent system (never pooled)
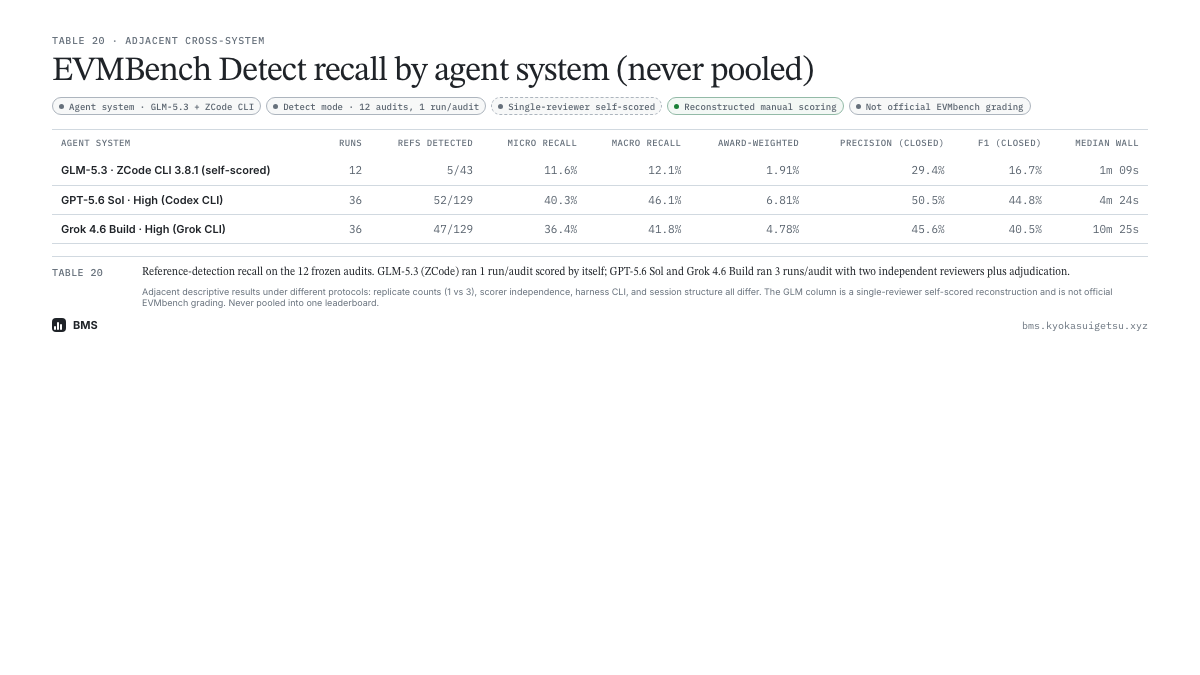
Reference-detection recall on the 12 frozen audits. GLM-5.3 (ZCode) ran 1 run/audit scored by itself; GPT-5.6 Sol and Grok 4.6 Build ran 3 runs/audit with two independent reviewers plus adjudication.
Table 20 · Adjacent cross-system
EVMBench Detect recall by agent system (never pooled)
| Agent system | Runs | Refs detected | Micro recall | Macro recall | Award-weighted | Precision (closed) | F1 (closed) | Median wall |
|---|---|---|---|---|---|---|---|---|
| GLM-5.3 · ZCode CLI 3.8.1 (self-scored) | 12 | 5/43 | 11.6% | 12.1% | 1.91% | 29.4% | 16.7% | 1m 09s |
| GPT-5.6 Sol · High (Codex CLI) | 36 | 52/129 | 40.3% | 46.1% | 6.81% | 50.5% | 44.8% | 4m 24s |
| Grok 4.6 Build · High (Grok CLI) | 36 | 47/129 | 36.4% | 41.8% | 4.78% | 45.6% | 40.5% | 10m 25s |
Adjacent descriptive results under different protocols: replicate counts (1 vs 3), scorer independence, harness CLI, and session structure all differ. The GLM column is a single-reviewer self-scored reconstruction and is not official EVMbench grading. Never pooled into one leaderboard.