Shareable benchmark table
PoolTogether pilot metrics
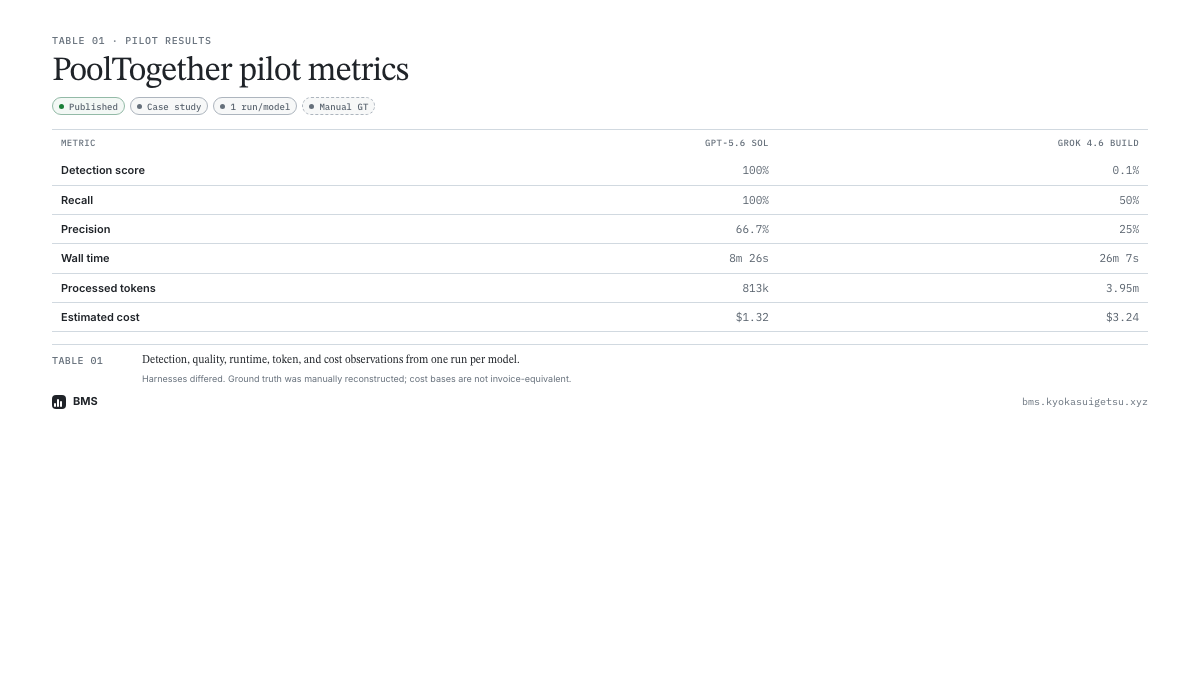
Detection, quality, runtime, token, and cost observations from one run per model.
Table 01 · Pilot results
PoolTogether pilot metrics
| Metric | GPT-5.6 Sol | Grok 4.6 Build |
|---|---|---|
| Detection score | 100% | 0.1% |
| Recall | 100% | 50% |
| Precision | 66.7% | 25% |
| Wall time | 8m 26s | 26m 7s |
| Processed tokens | 813k | 3.95m |
| Estimated cost | $1.32 | $3.24 |
Harnesses differed. Ground truth was manually reconstructed; cost bases are not invoice-equivalent.