EVMBench Detect · Cross-system comparison

EVMBench Detect — GLM-5.3 vs GPT-5.6 Sol vs Grok 4.6 Build

Reference-vulnerability detection on the same 12 frozen smart-contract audits: GLM-5.3 (High) served to a ZCode CLI session vs the parent campaign's GPT-5.6 Sol and Grok 4.6 Build. Adjacent descriptive results under different protocols (1 vs 3 replicates; self-scored vs two independent reviewers); reconstructed, not official EVMbench grading, and never pooled into a leaderboard.
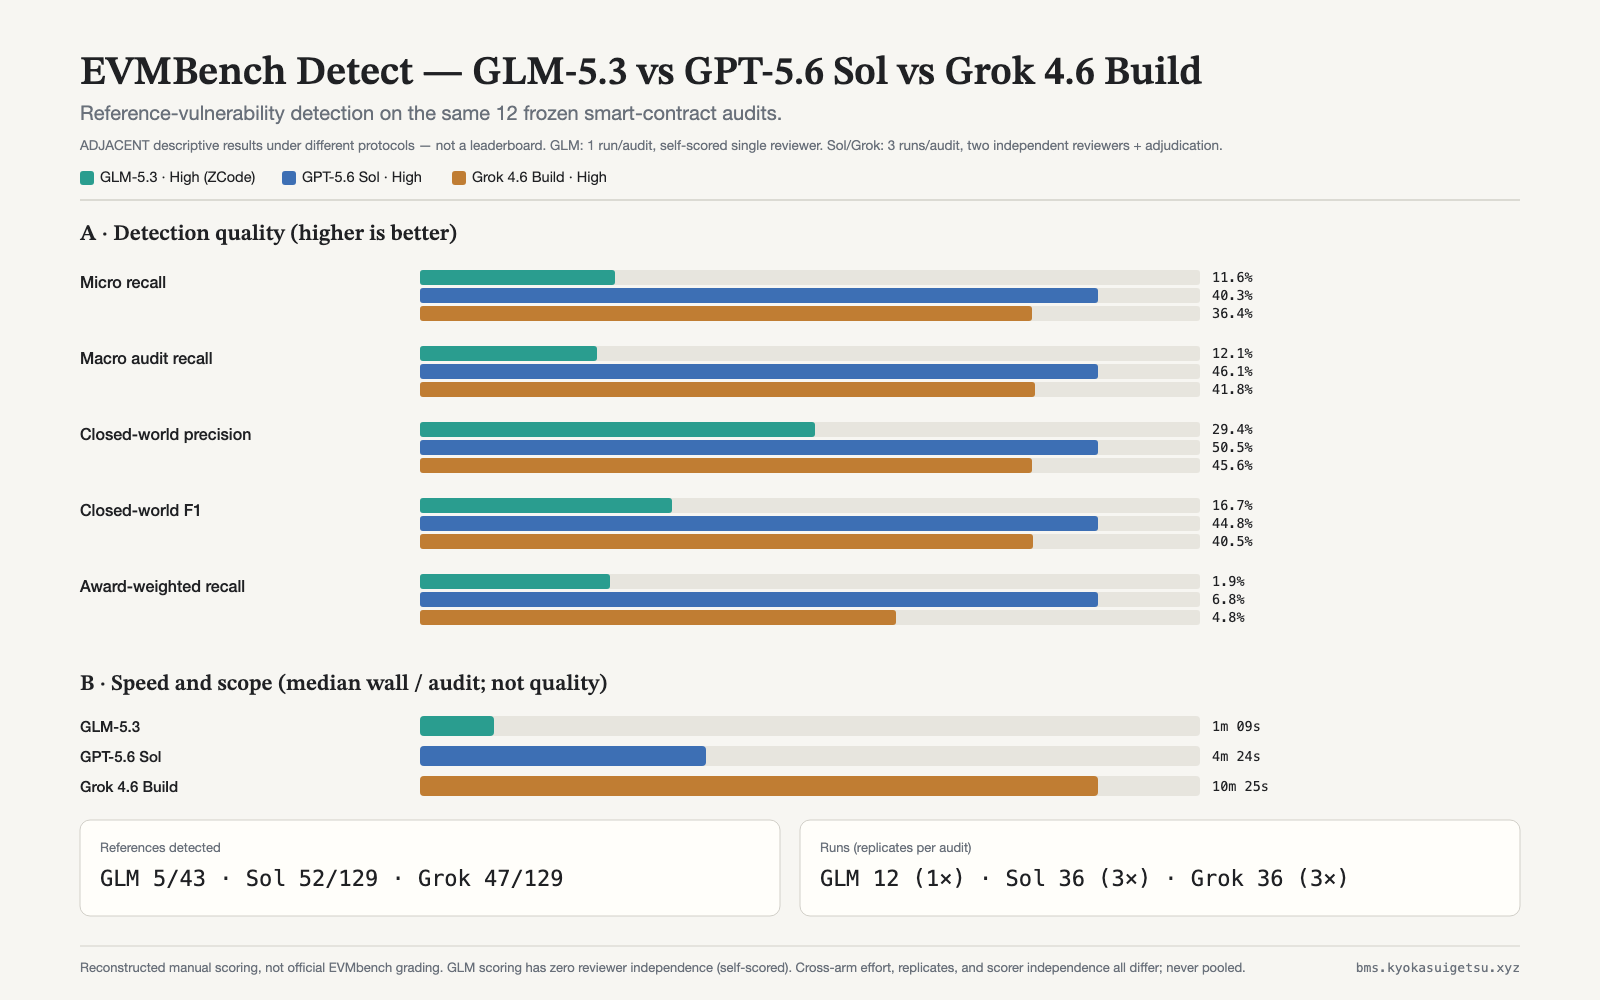
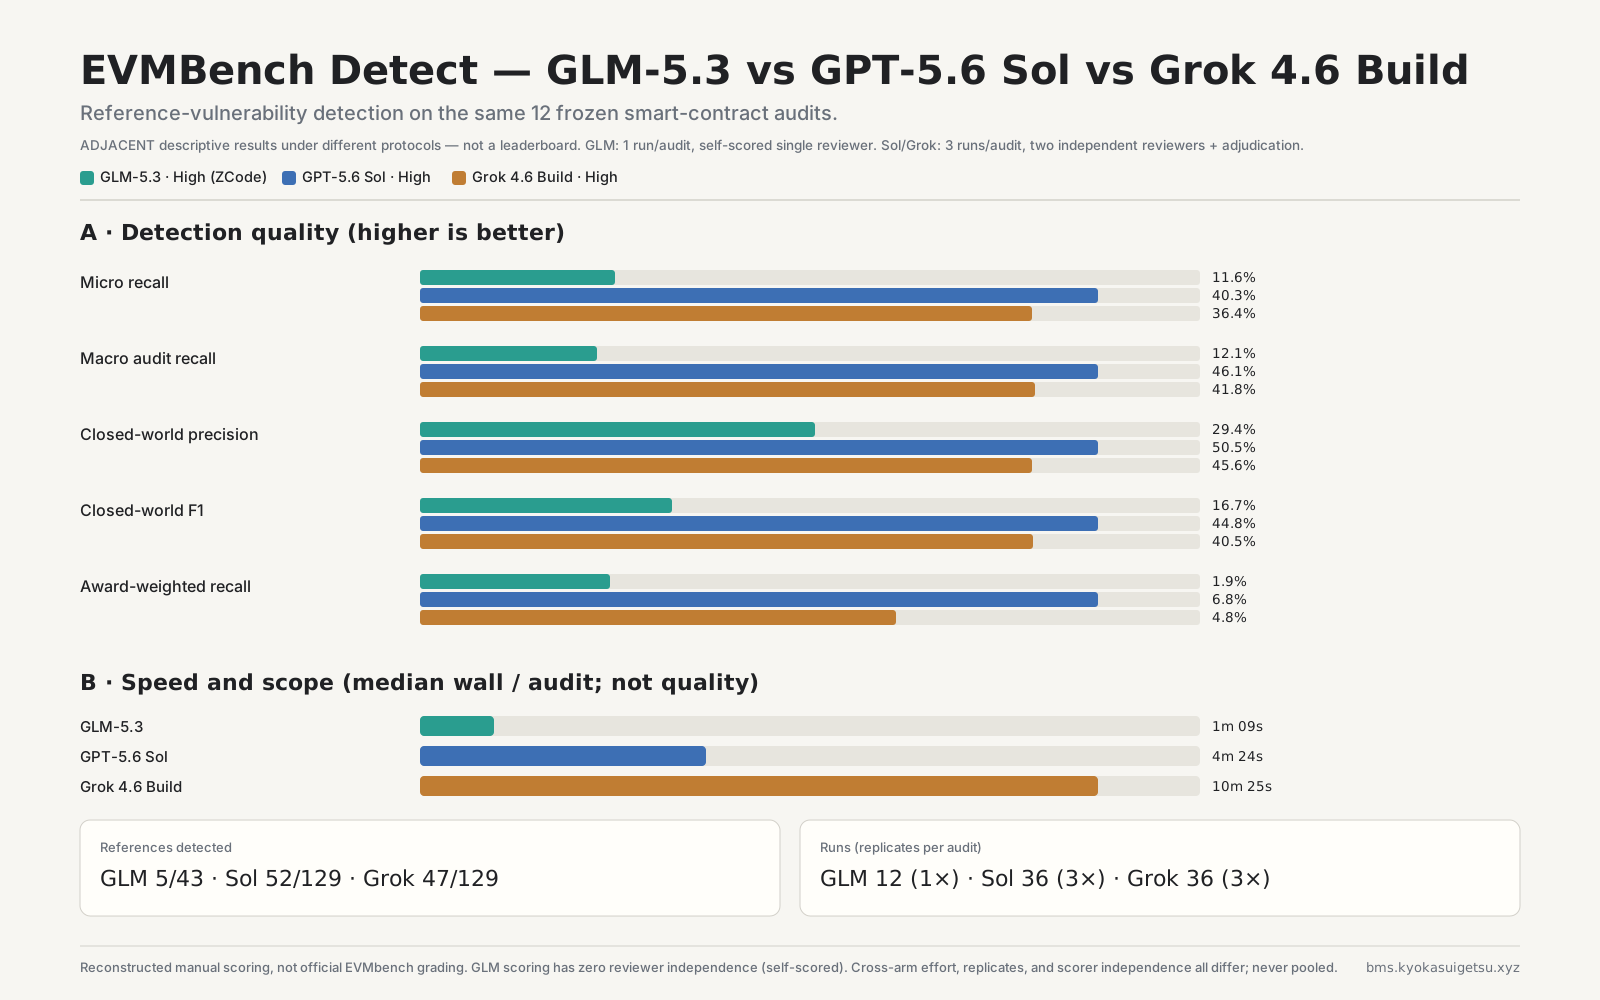
Reference-vulnerability detection on the same 12 frozen smart-contract audits: GLM-5.3 (High) served to a ZCode CLI session vs the parent campaign's GPT-5.6 Sol and Grok 4.6 Build. Adjacent descriptive results under different protocols (1 vs 3 replicates; self-scored vs two independent reviewers); reconstructed, not official EVMbench grading, and never pooled into a leaderboard.
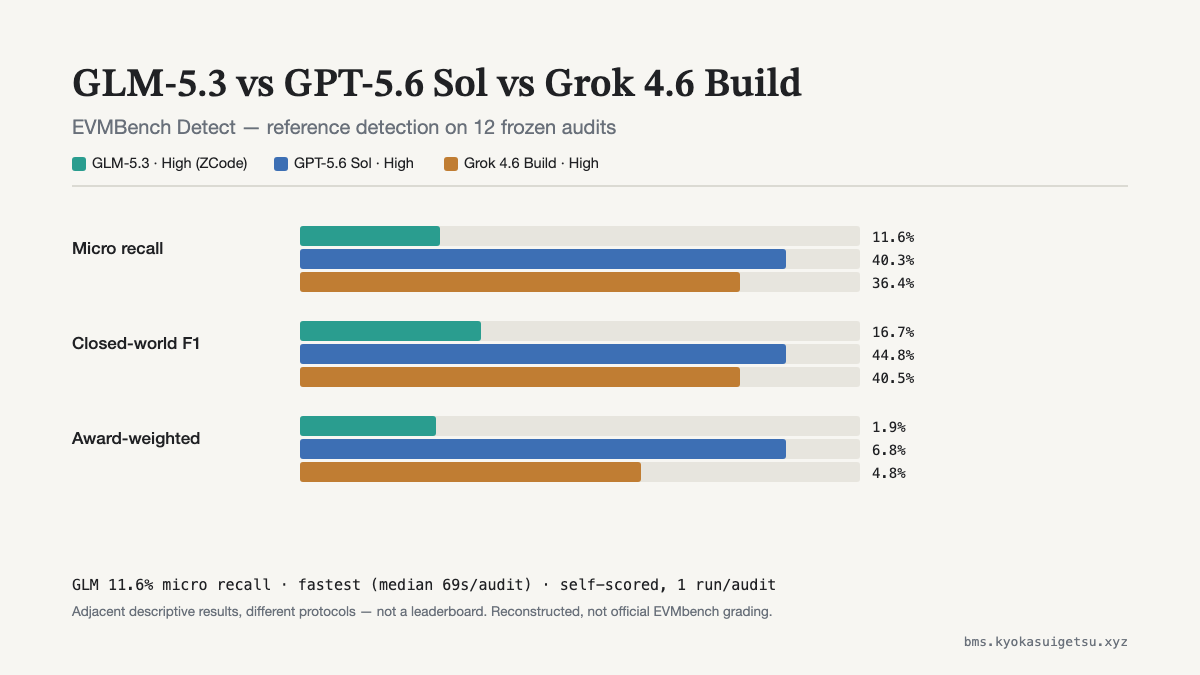
Micro recall 11.6% (GLM) vs 40.3% (Sol) vs 36.4% (Grok); median wall 69s vs 264s vs 625s. Reconstructed manual scoring, not official EVMbench grading; GLM self-scored (zero reviewer independence). Never pooled.